ElevenLabs text-to-speech in Galleria: end-to-end test evidence
Eleven v4 and Eleven Turbo v2.5 generate, play, bill per character and produce captions, from the real UI through to the credit ledger. Two results were not a clean pass; neither is a defect in this work.
After the first run the change set was audited for scope and workarounds, trimmed, and the affected paths were run again. This page shows the final state.
Run against the feature branch's own binaries on the make up stack. Every claim below was checked in the database or a service log, not taken from the screen.
What each hop was shown to do
- exercised
Galleria UI
Controls, live counter, live quote, over-limit block, playback, captions panel - exercised
Gateway
400 before the credit gate over the limit; fal dispatch; quote from the prompt length - exercised
go-queue
One start and one completed line per generation; failures archived, not retried - exercised
vertex-ai to fal
Only the model's own keys forwarded; Auto language sends nothing - exercised
Storage
MP3 stored and served; word timings saved on the asset - exercised
go-credits
Cost-plus per character; one usage row per generation - exercised
Public API
Neither new model is listed; Seed Audio and every other model as before - exercised
MCP list_models
Called over HTTP: same result as the public list
Quote equals charge
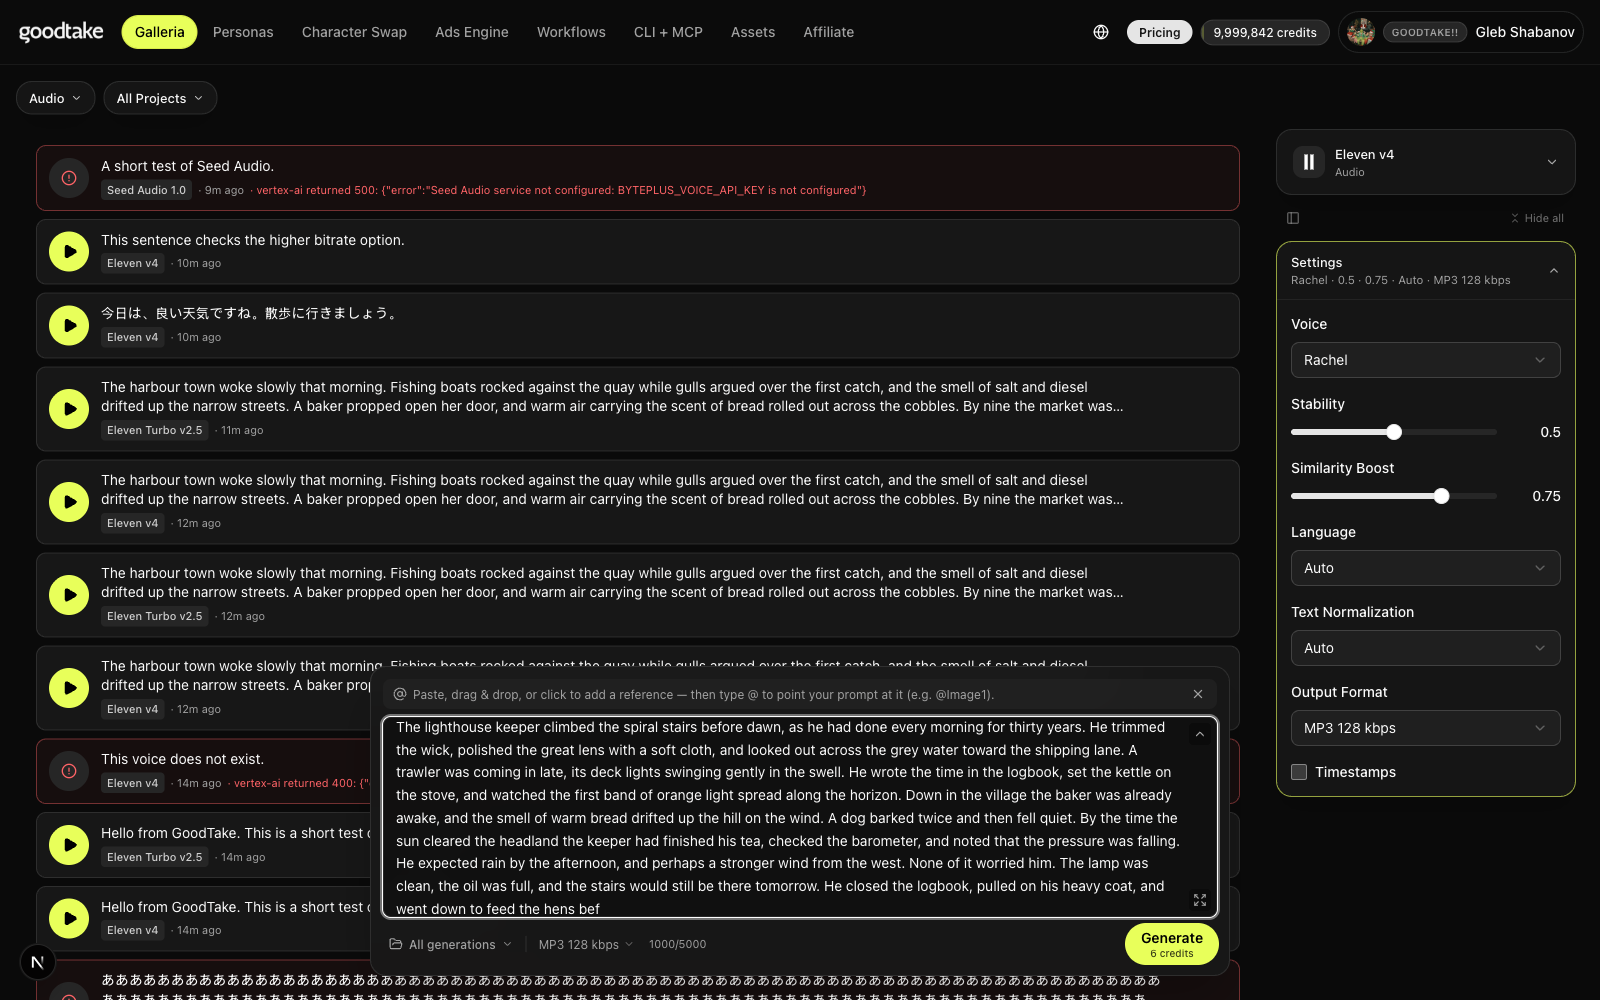
For every completed generation the credits charged in credit_ledger equal what the estimate returned for the same character count, on the cost_plus pricing path, with exactly one usage row.
| Model | Characters | Quote | Charged | Provider cost | Time | Driven by |
|---|---|---|---|---|---|---|
| Eleven v4 | 60 | 1 | 1 | $0.004800 | 3.8 s | API |
| Eleven v4 | 62 | 1 | 1 | $0.004960 | 4.4 s | Browser |
| Eleven v4 | 1,013 | 6 | 6 | $0.081040 | 16.6 s | API |
| Eleven v4 | 5,000 | 27 | 27 | $0.400000 | 62.8 s | API |
| Eleven Turbo v2.5 | 60 | 1 | 1 | $0.003000 | 2.9 s | API |
| Eleven Turbo v2.5 | 62 | 1 | 1 | $0.003100 | 3.4 s | Browser |
| Eleven Turbo v2.5 | 1,013 | 4 | 4 | $0.050650 | 6.3 s | API |
| Eleven Turbo v2.5 | 5,000 | 17 | 17 | $0.250000 | 12.6 s | API |
Four more short generations were each quoted and charged 1 credit: a 22-character Japanese sentence and a 47-character 192 kbps run on v4, and one 39-character run per model and a final 38-character v4 run after the scope passes. Turbo accepted 5,000 characters, which fal does not document; bytes per character matched the 1,013-character run, so nothing was truncated.
In the browser
| Check | Result | What was observed |
|---|---|---|
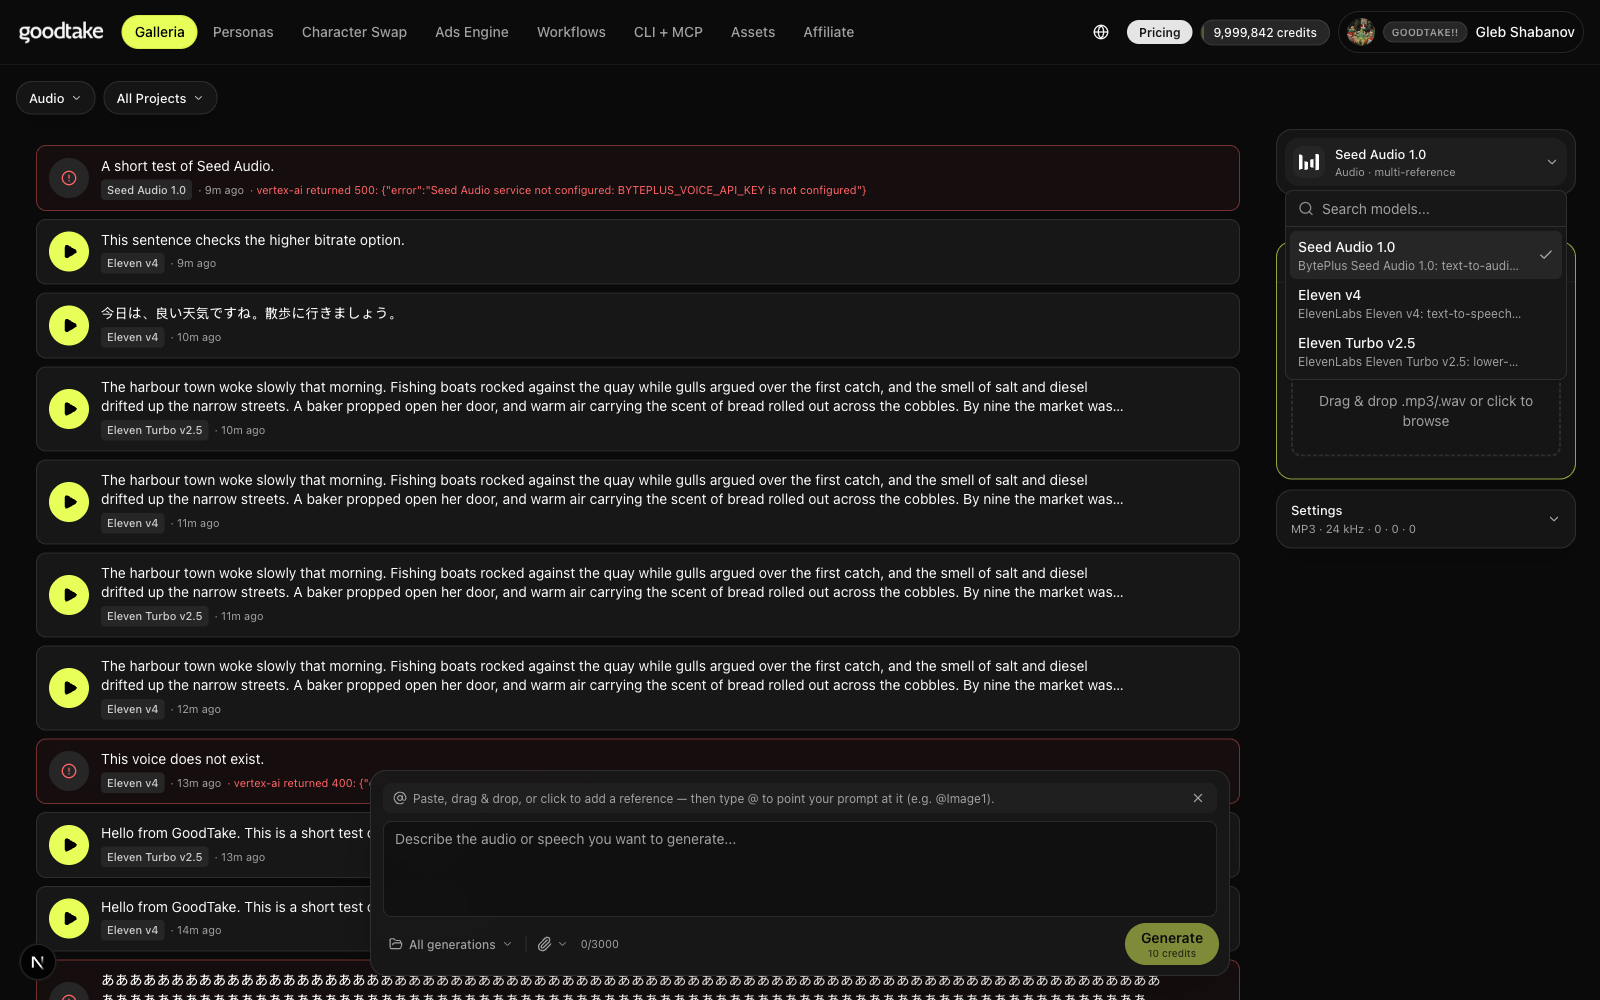
| Audio models in the picker | partial | Seed Audio 1.0 (default), Eleven v4, Eleven Turbo v2.5 are listed. The option list shows no per-model logos; the Image picker is the same, so this is the shared picker's existing behaviour. The logo appears on the selected model's card. |
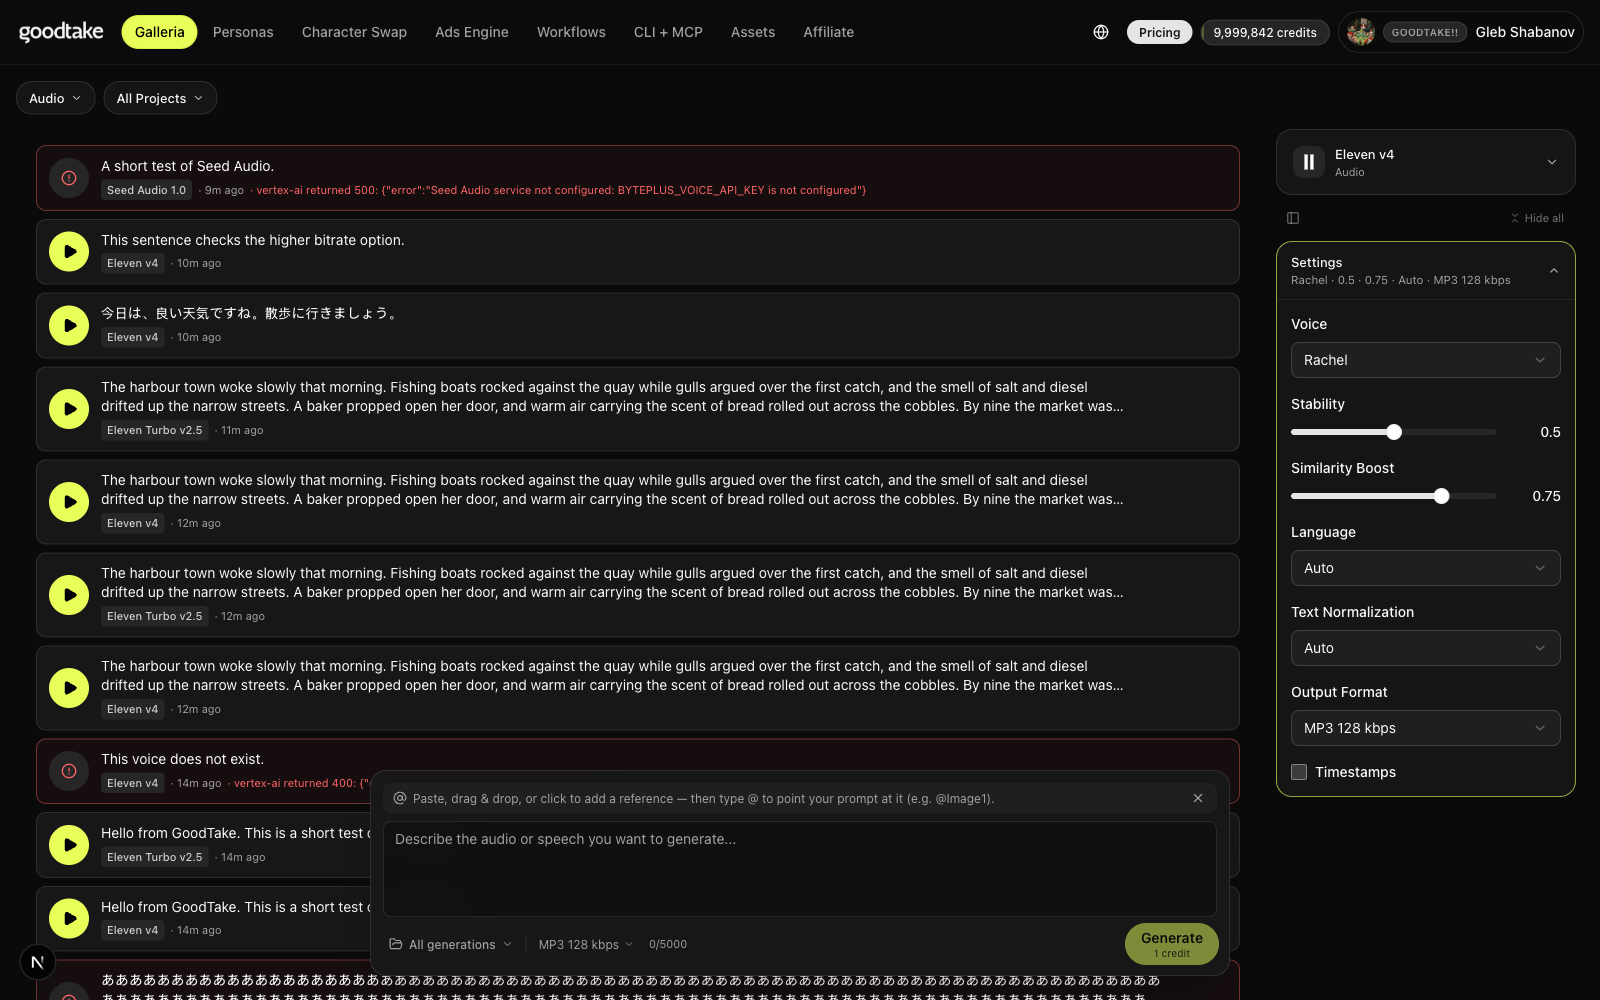
| Eleven v4 settings | pass | Voice (21 options, Rachel default), Stability 0.5, Similarity Boost 0.75, Language (Auto + 32), Text Normalization, Output Format (MP3 128 / 192 kbps), Timestamps. Every list control is a dropdown. |
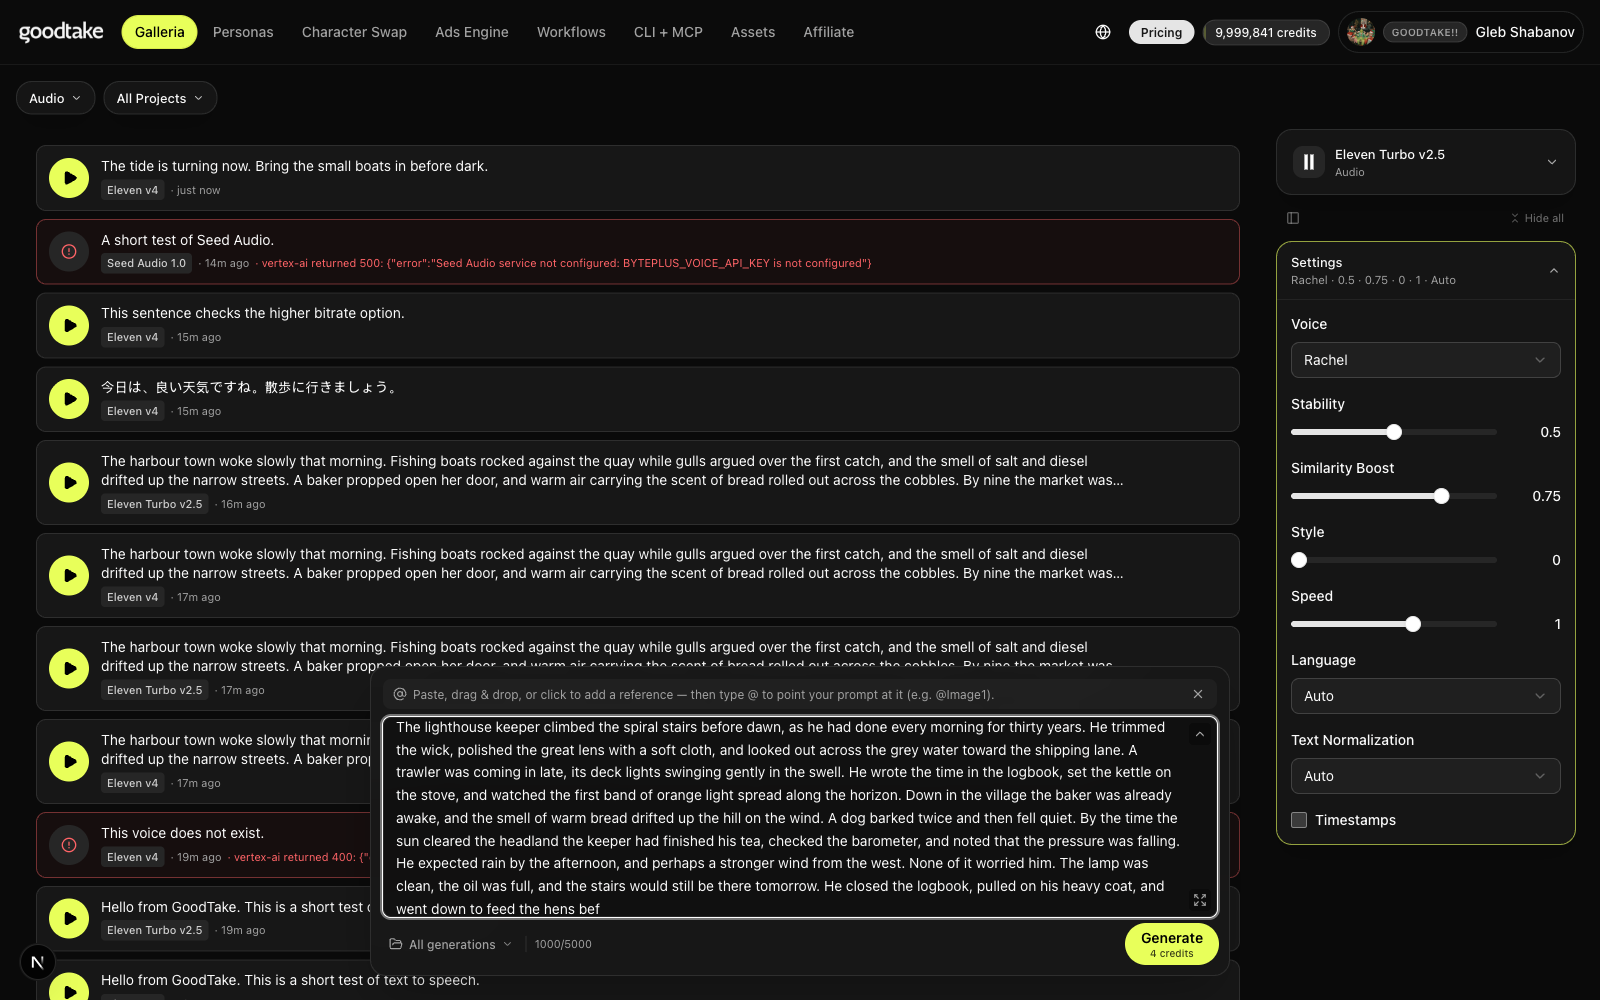
| Counter and live quote | pass | The count is visible at every length on both new models: 0/5000, 62/5000 (1 credit), 1000/5000 (6 credits) in the floating composer, and Max 5000 characters · n/5000 in the sidebar layout. Each estimate request carried characters equal to the counter. |
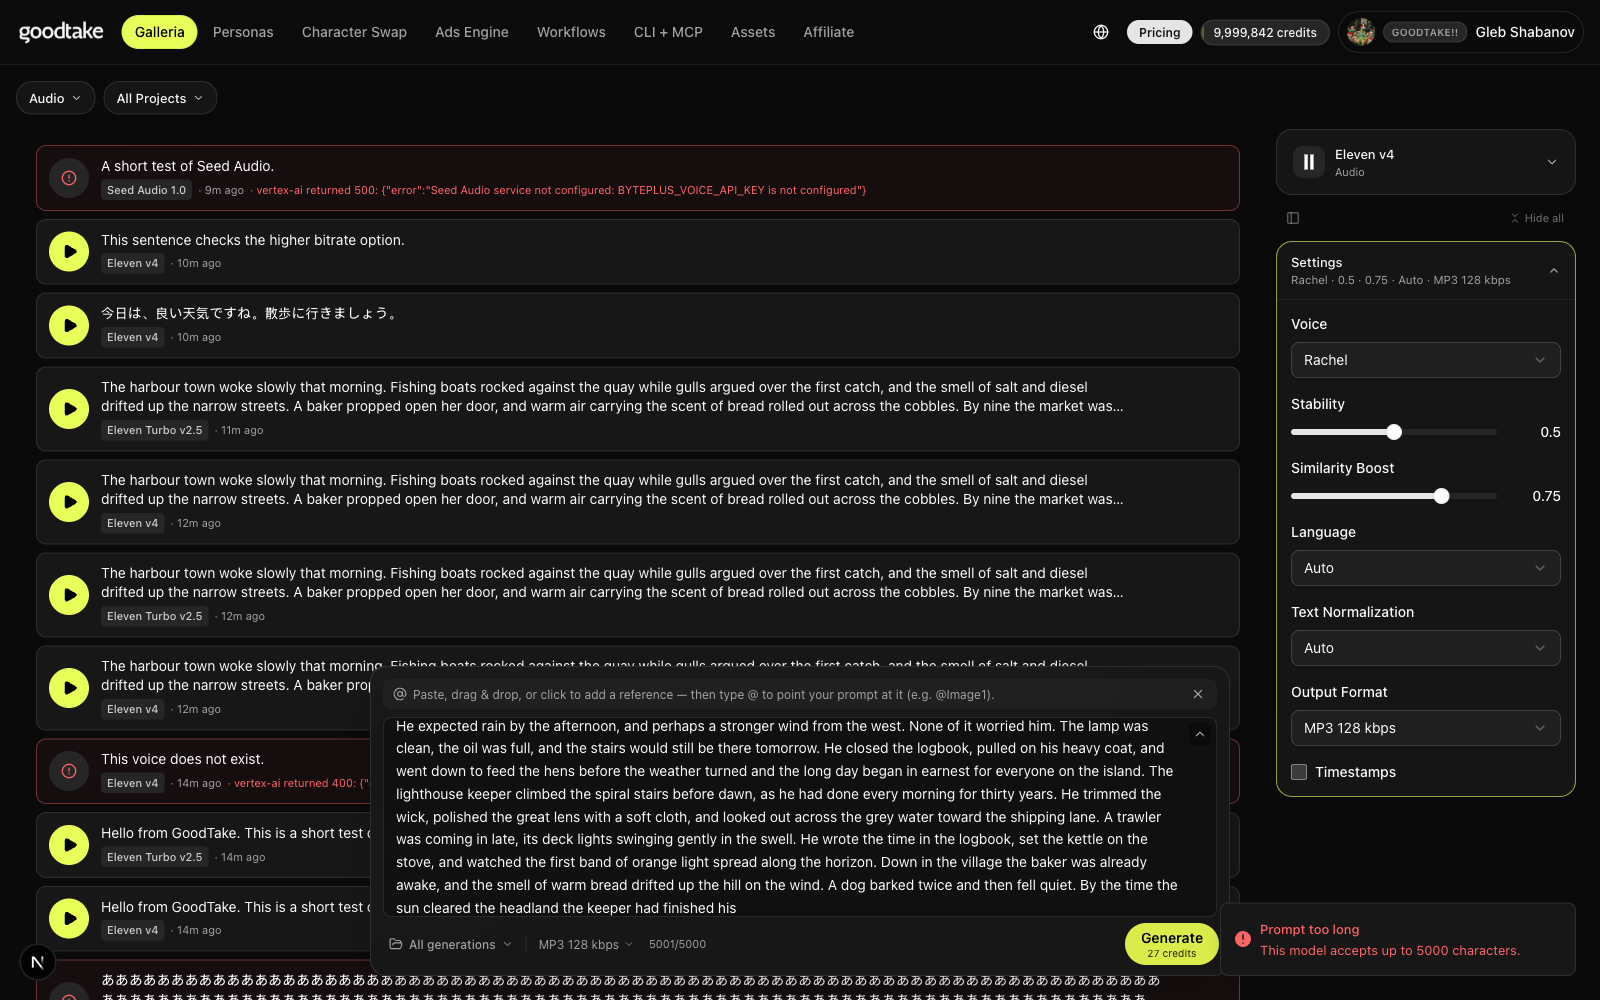
| Over the limit | pass | 5001/5000, toast "Prompt too long", no generation request sent, generation count unchanged in the database. |
| Generate, play, captions on v4 | partial | Row appeared without a reload, audio played (current time advanced 0.106 s to 1.222 s), captions panel listed two cues, SRT and VTT downloaded and are valid. The last cue ends 31 ms after the audio file does; see below. |
| Eleven Turbo v2.5 | pass | Same shared controls plus Style and Speed, no Output Format. 1,000 characters quotes 4. Generate, play, captions and both downloads pass, including the duration check. |
| Rows without timestamps | pass | The captions toggle is on exactly the five rows whose asset has timestamps in the database. Failed rows show only recreate and delete. |
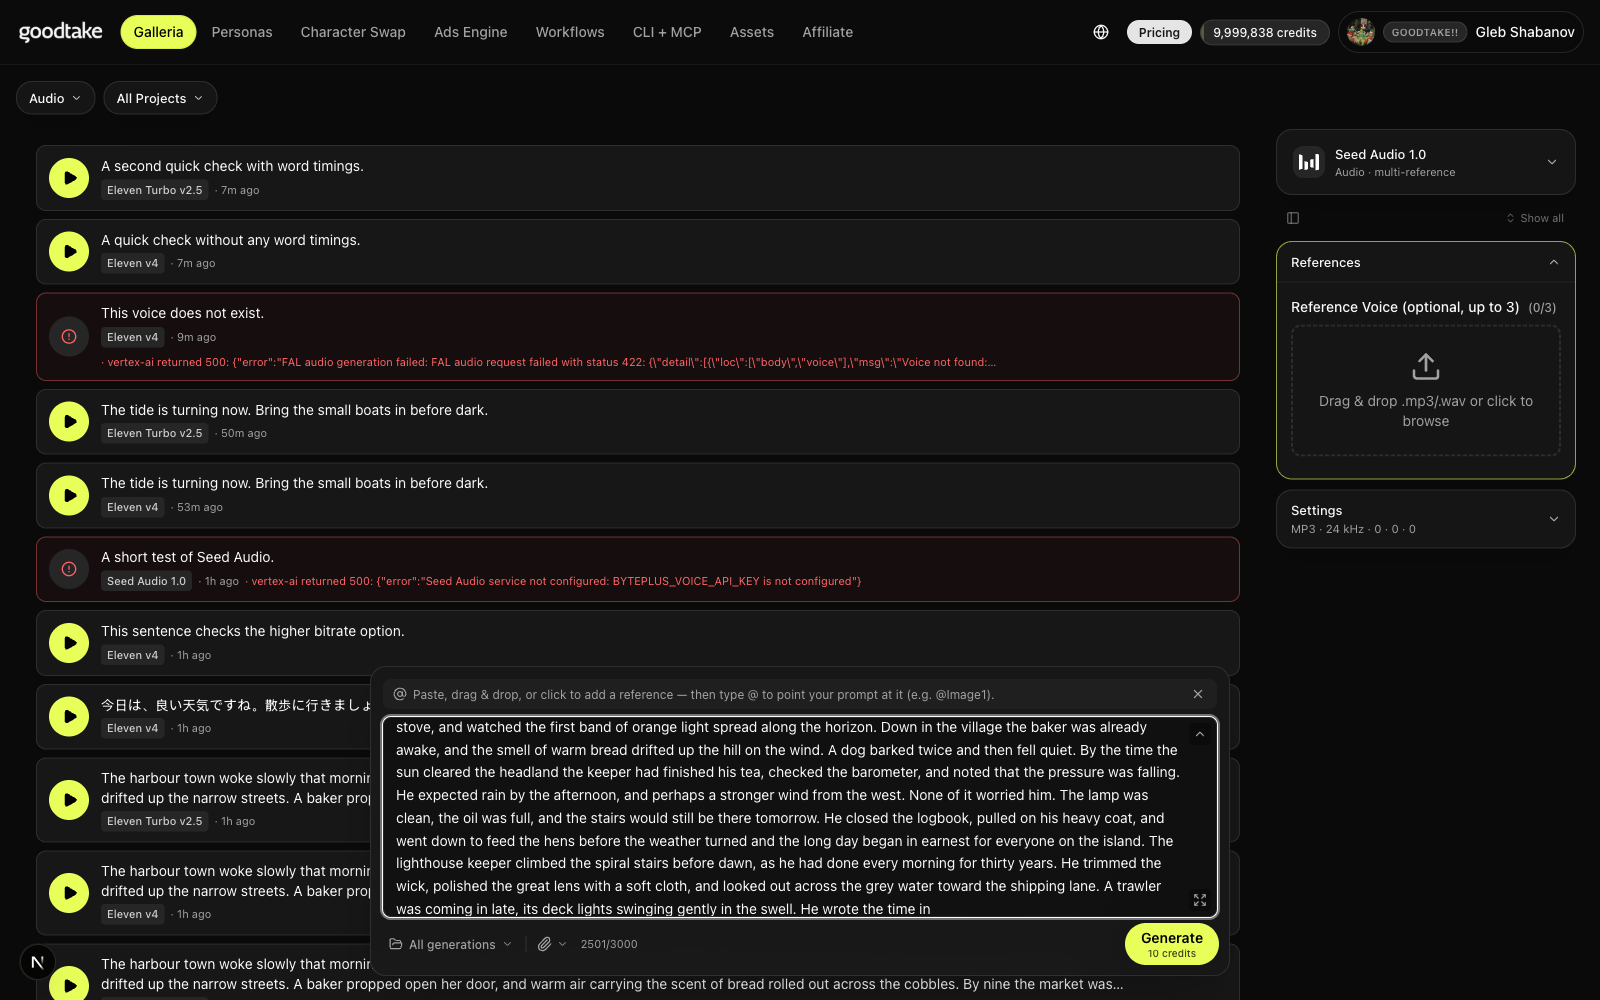
| Seed Audio 1.0 | pass | Identical to main. Max 3000 characters in the sidebar, the count appearing only past 2,500 (absent at 2,500, 2501/3000 at 2,501) and counting the raw text, spaces included (2504/3000 with five trailing spaces). 3,001 characters is blocked with its original message, "Seed Audio prompts must be 3000 characters or fewer.", and no request. Quote is 10 credits. |
| Switching models | pass | Settings reset to defaults on every switch. No v4 key reached a Turbo request or the reverse. |
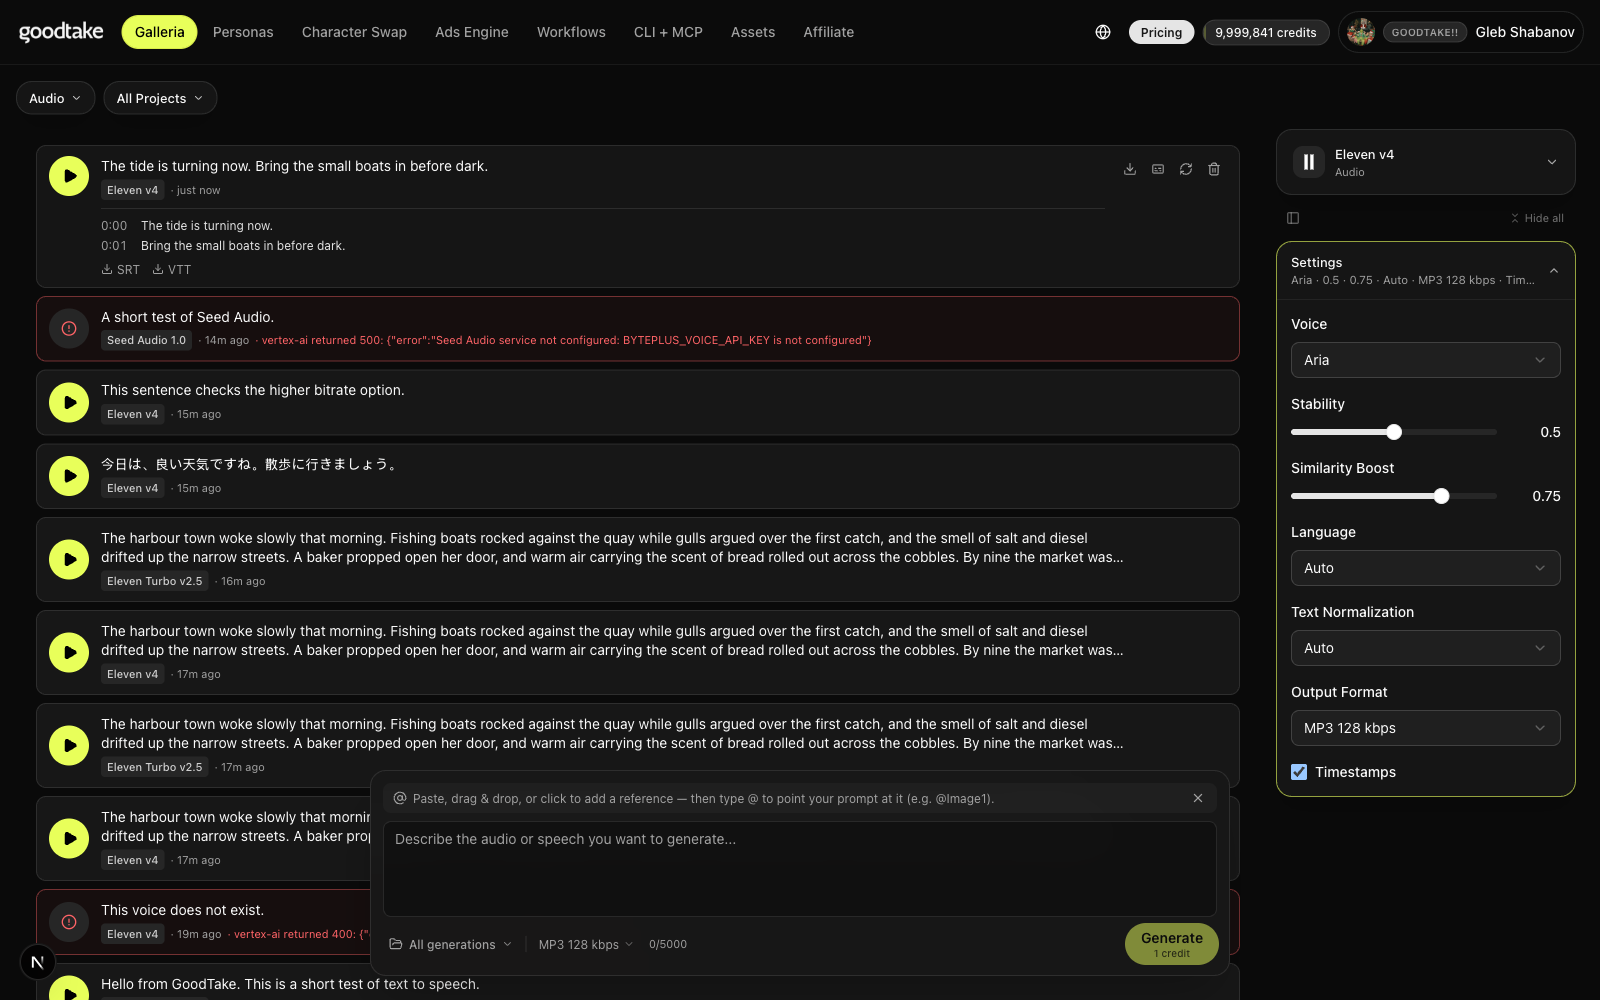
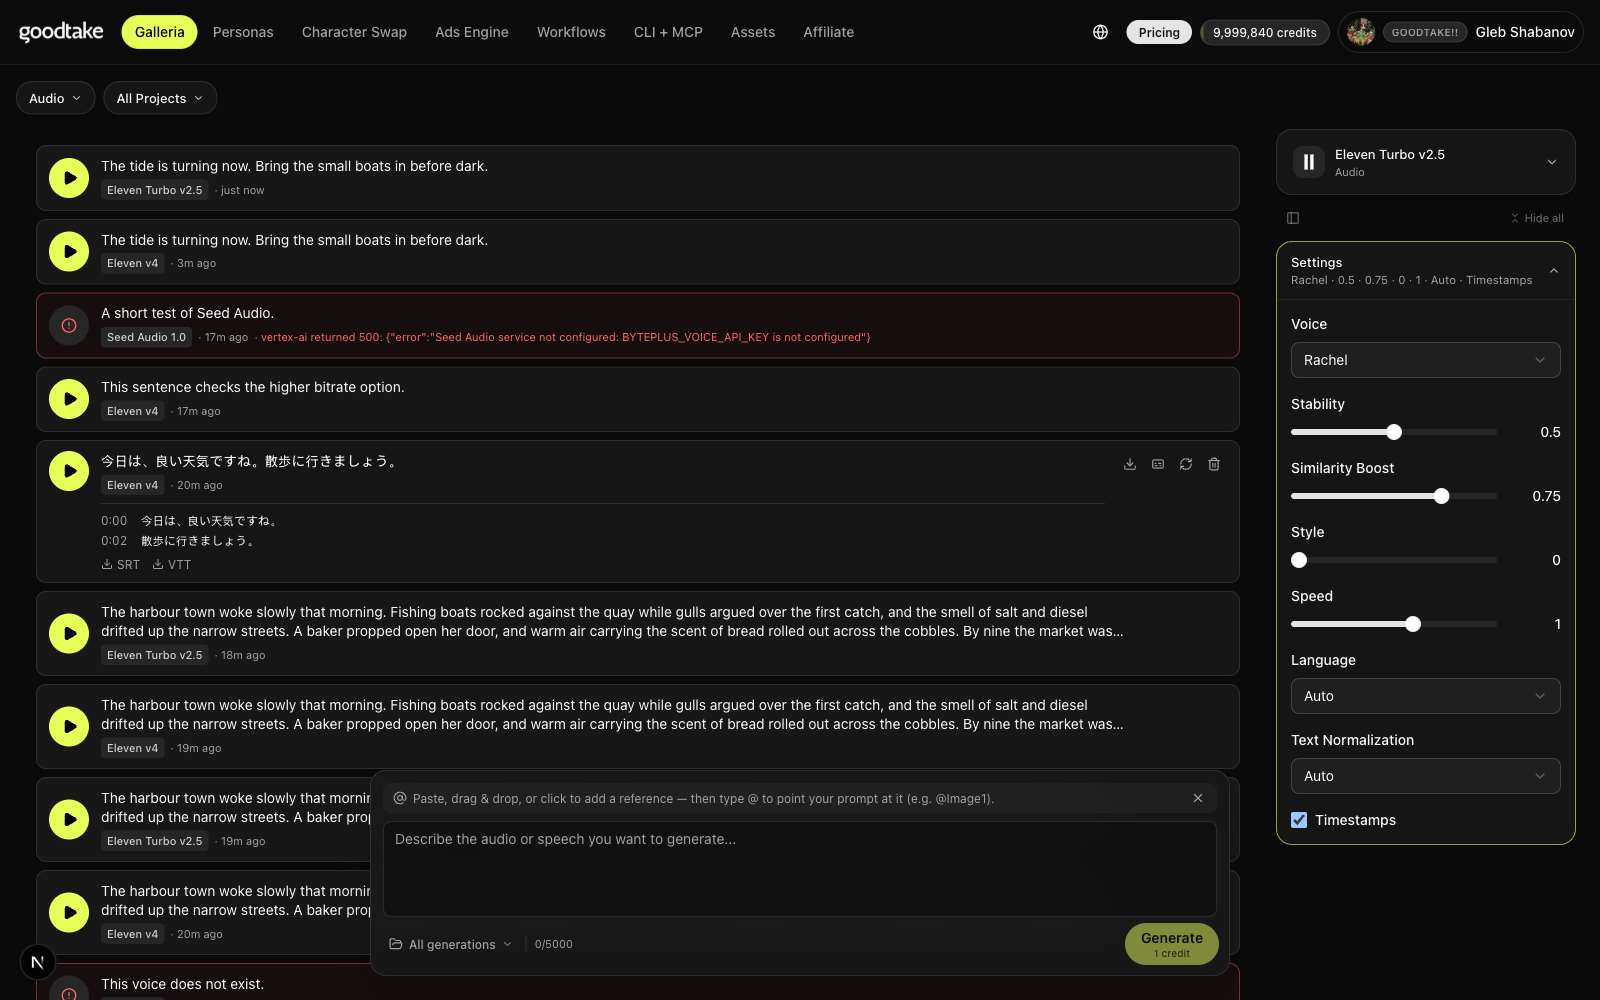
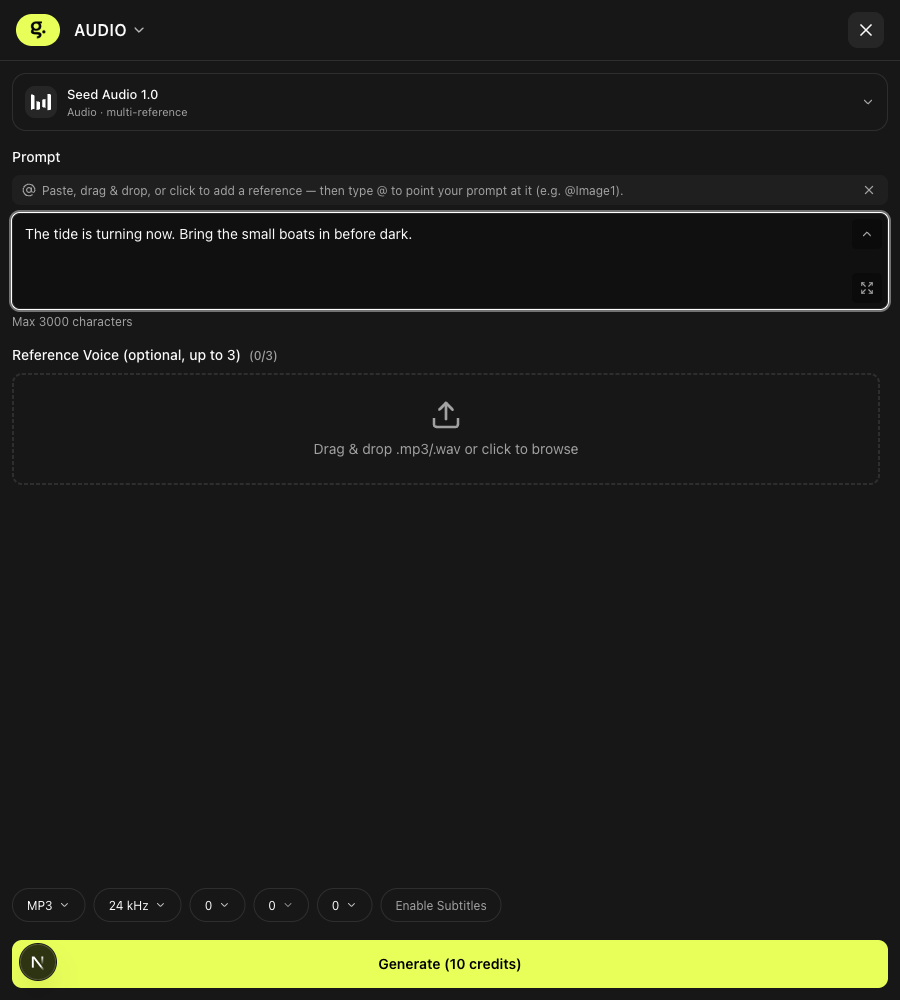
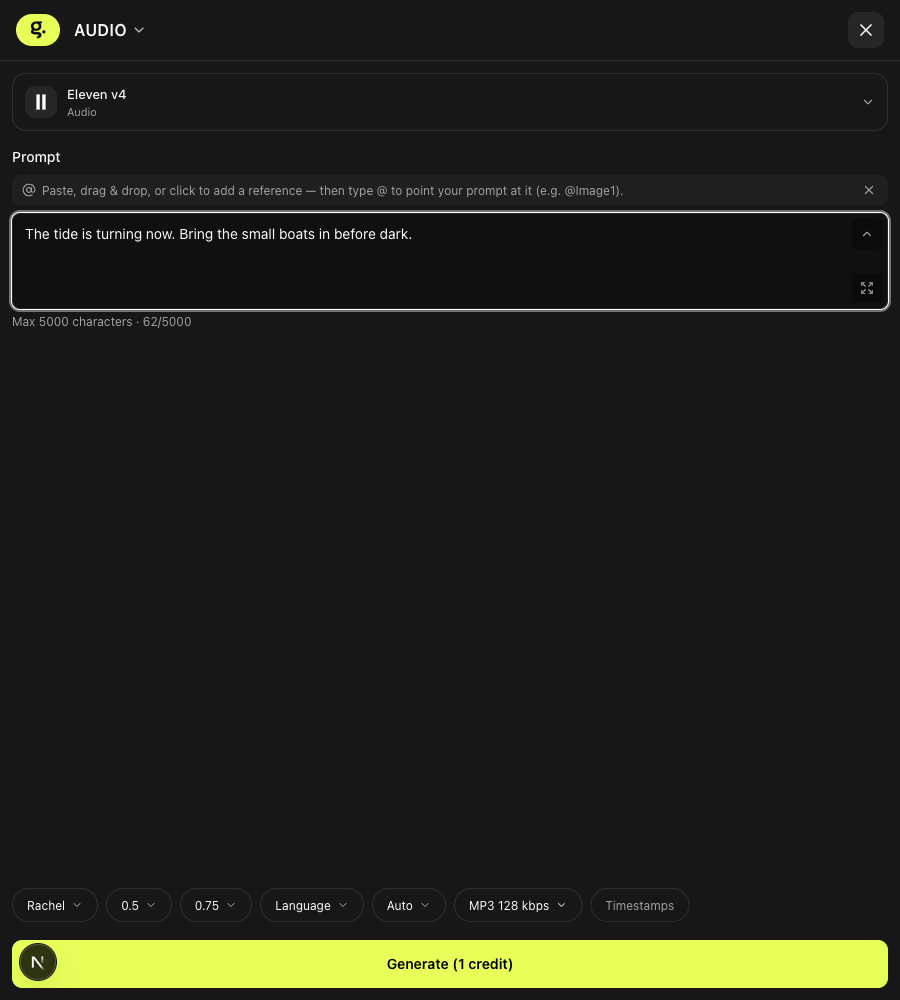
The two generations made in the browser
Prompt for both: "The tide is turning now. Bring the small boats in before dark." (62 characters). Press play to hear what was stored.
Eleven v4, voice Aria
57df9972 · 4.049 s · mp3 44.1 kHz 128 kbpsEleven Turbo v2.5, voice Rachel
05312794 · 3.474 s · mp3 44.1 kHz 128 kbpsRequest bodies captured from the browser
POST /api/generations  ->  201   (Eleven v4)
{"user_id":"7c1e96fa-…","model_id":"4b89989b-…","prompt":"The tide is turning now. Bring the small boats in before dark.",
 "config":{"voice":"Aria","stability":0.5,"similarity_boost":0.75,"language_code":"","apply_text_normalization":"auto",
           "output_format":"mp3_44100_128","timestamps":true},
 "asset_type":"audio","action":"generate","organization_id":"036bb424-…"}

POST /api/generations  ->  201   (Eleven Turbo v2.5)
{"user_id":"7c1e96fa-…","model_id":"2263156a-…","prompt":"The tide is turning now. Bring the small boats in before dark.",
 "config":{"voice":"Rachel","stability":0.5,"similarity_boost":0.75,"style":0,"speed":1,"language_code":"",
           "apply_text_normalization":"auto","timestamps":true},
 "asset_type":"audio","action":"generate","organization_id":"036bb424-…"}
Live quote requests
POST /api/credits/estimate   {"model_identifier":"eleven-v4-tts", … ,"characters":62,   "config":{…}}
  -> {"credits":"1","cogs_usd":"0.00496","pricing_path":"cost_plus","estimated":false}
POST /api/credits/estimate   {"model_identifier":"eleven-v4-tts", … ,"characters":1000, "config":{…}}
  -> {"credits":"6","cogs_usd":"0.08","pricing_path":"cost_plus","estimated":false}
POST /api/credits/estimate   {"model_identifier":"eleven-turbo-v2.5-tts", … ,"characters":1000, "config":{…}}
  -> {"credits":"4","cogs_usd":"0.05","pricing_path":"cost_plus","estimated":false}
Empty prompt (no characters key)
  -> {"credits":"1","pricing_path":"flat_fallback","estimated":false}
What vertex-ai sent to fal
Auto language put an empty language_code in the request, and vertex-ai dropped it: neither line below carries the key.
[FAL Audio] model=eleven-v4-tts path=elevenlabs/tts/eleven-v4 chars=62
  params=map[apply_text_normalization:auto output_format:mp3_44100_128 similarity_boost:0.75 stability:0.5 timestamps:true voice:Aria]
[FAL Audio] stored audio path=gs://goodtake_ai_dev/audios/fal-tts/fal_tts_91851304_20261004_162728.mp3 content_type=audio/mpeg

[FAL Audio] model=eleven-turbo-v2.5-tts path=fal-ai/elevenlabs/tts/turbo-v2.5 chars=62
  params=map[apply_text_normalization:auto similarity_boost:0.75 speed:1 stability:0.5 style:0 timestamps:true voice:Rachel]
[FAL Audio] stored audio path=gs://goodtake_ai_dev/audios/fal-tts/fal_tts_c8fd8df8_20261004_163025.mp3 content_type=audio/mpeg
Database
| Generation | Model | Status | Chars | Timing entries | Usage rows | Charged | Billed cost | Balance after |
|---|---|---|---|---|---|---|---|---|
| 57df9972-e603-… | eleven-v4-tts | completed | 62 | 12 | 1 | 1.0000 | 0.004960 | 9,999,841 |
| 05312794-242e-… | eleven-turbo-v2.5-tts | completed | 62 | 12 | 1 | 1.0000 | 0.003100 | 9,999,840 |
Concatenating the 12 stored word values of either asset gives the prompt back exactly. The go-credits spend lines for both read path=cost_plus; go-queue logged one start and one completed line per id.
Downloaded caption files
1
00:00:00,000 --> 00:00:01,720
The tide is turning now.

2
00:00:01,920 --> 00:00:04,080
Bring the small boats in before dark.
WEBVTT

00:00:00.000 --> 00:00:01.720
The tide is turning now.

00:00:01.920 --> 00:00:04.080
Bring the small boats in before dark.
1
00:00:00,070 --> 00:00:01,277
The tide is turning now.

2
00:00:01,486 --> 00:00:03,181
Bring the small boats in before dark.
1
00:00:00,000 --> 00:00:02,320
今日は、良い天気ですね。

2
00:00:02,320 --> 00:00:03,520
散歩に行きましょう。
Driven through the API
| Check | Result | Evidence |
|---|---|---|
| Limit counts characters, before the gate | pass | 5,001 characters: HTTP 400 text is 5001 characters; the limit for this model is 5000, no generation row, no ledger row. 5,000 Japanese characters (15,000 bytes) passed the limit. |
| Short generation with timestamps, both models | pass | 12 entries of {word, start_s, end_s}, identical in the API response and the database. |
| Unknown voice fails once, no charge | pass | Failed within 2 s. One attempt in the queue log; the task is archived, not in the retry set. No ledger row. The stored message is fal's raw "Voice not found" error inside the worker's wrapper; the UI cannot send an unknown voice today. |
| No timestamps requested, none stored | pass | The asset's provider_metadata has no timestamps key, in the database and through the API. With timestamps requested, 7 entries were stored that rebuild the prompt. |
| Quote equals charge at 1,013 and 5,000 characters | pass | See the table above. |
| v4 options | pass | language_code: ja works. mp3_44100_192 returns a 192 kbps MP3 (ffprobe). |
| Not listed publicly | pass | GET /public/v1/models?type=audio: 200, listing only seed-audio-1.0. MCP list_models {type: "audio"}: the same. type=image (10) and type=video (19) are unchanged. The in-app model list includes both new models. |
| Seed Audio 1.0 unchanged | pass | Accepted, routed to /bytedance/generate-audio, fails with "not configured" because the local BytePlus key is unset, exactly as before. No charge. |
| Migration 123 rollback on seeded data | pass | Down: version 122, both per-character rows deleted, constraint restored, 99 other cost rows byte-identical, price falls back to 1 credit. Up and re-seed: price back to 6 credits. |
Scope passes
The owner's rule: leave existing behaviour alone unless the new models needed it changed, keep the implementation simple, and remove workarounds. Three independent audits of the diff, and a line-by-line check by the reviewer, led to these changes. All are re-verified above.
- Back to exactly what
mainhas: the audio success toast, two comments in the pricing engine, the public API doc page, the Audio feed's empty-state sentence, a startup log line, Seed Audio's public listing, and all of Seed Audio's prompt-limit code (its check, its message, its counter and its config entry). - The new models carry their own limit. Their counter and over-limit check sit beside Seed Audio's rather than replacing it. Two existing conditions gained one term each, so the old "3000" blocks do not show on a 5,000-character model.
- The public list hides only the two new models. An earlier version rejected the whole audio type, which also delisted Seed Audio.
- Removed from the new code: a second null filter in the queue worker (the gateway already filters once), and an error type in vertex-ai whose 400-or-500 distinction nothing read.
Minimal-diff audit, 6 October. A fresh independent reviewer read every changed hunk against main. Two things touched existing material without need and were undone: a helper that had been extracted out of Seed Audio's enqueue function (that function is byte-identical to main again; the new function carries its own copy of the call, as the image and video ones do), and another ticket's route (/dashscope/generate-video) that the regenerated API docs had picked up. The panel now counts characters only for models that carry their own limit, so image, video and Seed Audio renders run none of the new counting code. After the changes one live Turbo generation was charged exactly its quote, and the panel counted and quoted as before in both layouts.
Audit of the added code, 6 October. A second independent reviewer classified every added line as required, convention, optional or redundant. Removed as unneeded: a frontend flag that always travelled with the text limit, a duplicate unknown-model check in the speech route (the service already rejects it), and most of two documentation additions. Kept on purpose: the admin price preview, the quoted amount on the ledger, the splitting of Japanese and Chinese captions, the tests that are the only coverage of a contract, and the Language, Text Normalization and Output Format settings, which the ticket lists. The small test that pins which models are Galleria-only was removed in this pass and restored the same day, because the ticket asks for it. After the removals the panel counted and quoted exactly as before, and one live generation with timestamps was charged its quote.
The change set now modifies 17 lines that existed before it; everything else is addition. Each of the 17 is forced: four trailing commas, the audio handler's provider reject and enqueue call and two comment lines, the credit-gate call, the admin unit list with its message and one comment line, the pricing doc's unit list, one import, two counter conditions, and the Projects chat's model filter.
One difference remains for existing models, and no user can see it: the gateway sends the prompt's character count on every pricing request, not only for the new models. The engine reads it only for per-character rows. An image model's estimate was byte-identical with and without the field on all three pricing paths.
Is it Galleria only?
Yes, by the owner's definition: outside Galleria the two models cannot be selected in any picker and are not listed by the Claude connector. The Projects chat picker was the one place that listed them; it now hides these two models and nothing else. The last three rows are not places where a model is picked or listed for a user, and are left as on main.
| Surface | These two models | Same as Seed Audio on main |
|---|---|---|
| Galleria Audio tab | Listed, generate, play. The only UI that can run them. | yes |
| Public API, Claude connector (MCP), CLI: model lists | Not listed, for any type. Live list_models: audio returns only Seed Audio; image 9, video 17, default 9, none ElevenLabs. | no: Seed Audio is listed under type=audio, as before |
| Public API, MCP, CLI: generate | Refused; only image and video models are accepted, and there is no audio route | yes |
| Workflows | Not selectable. The add-node menu lists 10 image, 13 video and 2 video-edit models, no audio model (checked in the browser). | yes |
| Ads Engine, Personas, Character Swap, phone UI | Not offered | yes |
| Projects chat model picker | Not listed. The catalogue has 32 enabled models and the picker shows 30; the two missing are the ElevenLabs models. Its Audio tab shows only Seed Audio (checked in the browser, new and existing project). | no: Seed Audio is listed there, as before |
Public generations list and get, MCP list_generations and get_generation, Assets "All" | A clip made in Galleria is readable there by the same organisation: its text, the model identifier and the audio URL | yes |
| Model catalogue endpoints of the web app | Readable without login, by design for the signed-out Galleria picker | yes |
| The in-app create endpoint | Not tied to the Galleria page; any client with in-app access can call it | yes |
Two results that were not a clean pass
- Eleven v4's last caption cue ends 31 ms after the audio. The cue ends at 4.080 s; ffprobe measures the MP3 at 4.049 s. The files reproduce fal's word timing faithfully, and the same 31 to 46 ms overrun shows on every v4 asset measured, while Turbo assets stay inside. This is a difference between the provider's alignment data and the encoded file length. Players end the cue with the media.
- The picker's option list has no per-model logos. This is how the shared picker already renders for image and video models. The ElevenLabs mark loads correctly on the selected model's card.
Not tested
- Audible output from speakers. Playback was established from the audio element's state, and the stored MP3s are above.
- A browser generation with Timestamps off, 192 kbps, a named language, or non-default sliders. Those values were seen in quote requests and exercised through the API, not generated from the UI.
- The over-limit block on Turbo. It was tested on v4 and on Seed Audio.
- The row's audio Download, Recreate and Delete buttons.
- A real Seed Audio generation, the Japanese locale, and the mobile app.
- The sidebar layout beyond a quick look at 900 px, where the counter and quote behaved the same.